Published

canes, AI, and libraries

Why does it feel so scary to post here sometimes? It feels way scarier than it used to, the stakes feel really high. Maybe not “high” actually, just completely unknown.

At any rate, a few questions I’ve been asking myself recently.

* * *

Where can I find a good still-in-production cane? I love this book on walking sticks and canes from LMP, but none are widely in production (understandably, this was a speculative brief).

The folding cane by Michael Graves Design comes close but I’ve only been able to find the CVS branded version secondhand on eBay, and the color selection leaves something to be desired.

* * *

How do you factor AI tool costs in to your time-based rates as a contractor? Working with AI makes me more efficient (reducing my billable hours), improves the quality of my work (some might argue that, but I think it’s the case), and costs me hard cash. In theory the answer is just “raise your rates”, but I suspect most clients wouldn’t be able to stomach that. Maybe some would with a detailed policy / explanation, but that’s a lot to ask of most folks. Charge per token? Surely not.

I got talking with Sam about this last night, and then the same topic came up with GC spontaneously this morning. Maybe consider the subscription itself normal tooling overhead, absorb token-based usage up to a particular documented limit, then bill the client for major project-specific token usage. Even that last bit is so fiddly though. Back when we were focused on SB-PH we tended to take on fixed-fee projects, I feel like that’s probably the way for tight-scope, repeatable services.

More thinking to be done here.

* * *

What are some good books about the history of libraries? I’m curious how they evolved from private collections to previously-guaranteed-but-now-under-significant-threat public knowledge resources, and how that evolution could / should / shouldn’t influence future AI regulation. I’d love to read something that also covers the changing role of the librarian over time.

Analogous question: How did it come to be that computer + printer + internet access became a service that libraries are always assumed to offer? In the US, it seems like such a band-aid for the broader problem of internet access having nowhere near the protections that it should. How is it that the landline you’ve barely touched in a decade, if you even still have one, is more heavily protected than the utility you’re all but forced to use to file your taxes? Is there maybe a path forward with this considering the recent election results?

Thanks to @genericbecky.bsky.social for recommending The Library Book by Susan Orlean (and to @christian.bsky.social for relaying the rec!). The Library: A Fragile History also looks promising but sounds like it doesn’t go as deep on the the 20th+ century as I would like.


A post on the road to lupus diagnosis is still forthcoming. It’s almost impossible to write without sounding 100% more woe-is-me than I actually felt at the time, and to communicate the level of internal and external gaslighting involved. “Gaslighting” isn’t quite right though, it’s too strong a term for the usually-unintentional and mundane micro-invalidations. Death, or at least major illness, from a thousand cuts. I’ll think it through.
Published

How I hang stuff on old plaster and lath walls

Have finally been hanging a few things on the wall, and this is a note-to-self about how best to do that in our current home.

I’m more used to either plaster over masonry (UK) or more modern drywall and studs (US), but our apartment in an old Brooklyn brownstone is mainly plaster and wood lath over masonry. Very crumbly old plaster, surprisingly dense lath, and very little void space between the plaster+lath and the masonry. Hanging something is more art than science and requires a good understanding of what you’re working with.

Read more

Published

“When we simplify complex systems, we destroy them”

[Rewilding is] a fundamentally cheerful and workmanlike approach to what can seem insoluble problems. It doesn’t micromanage. It creates room for “ecological processes [which] foster complex and self-organizing ecosystems.” Rewilding puts into practice what every good manager knows: hire the best people you can, provide what they need to thrive, then get out of the way. It’s the opposite of command-and-control.

Worth reading: “We Need To Rewild The Internet”, an essay by Maria Farrell and Robin Berjon published two days ago on Noema Magazine’s site. Came across it via the ever-excellent Today in Tabs.

An essay about improving the internet that kicks off with an Ursula K. Le Guin quote is always going to have me from the start.

Salient bolded lessons from ecologists that technologists should adopt:

  • shifting baselines are real
  • complexity is not the enemy, it’s the goal
  • diversity is resiliance

Also, they raise an extremely important but often-neglected point that standards development organizations (SDOs) are “increasingly under the control of a few companies; so what appear to be “voluntary” standards are often the business choices of the biggest firms.”

***

Related reads:

See this Noema essay by Cory Doctorow.

Pls read “The Fediverse of Things”, a blog post by Terence Eden. Can’t remember who boosted this in to my Fedi timeline last week, but thank you whoever you are.

On the topic of infrastructure bottlenecks and maintenance: “The Cloud Under The Sea” by Josh Dzieza for The Verge. It’s about the undersea cables that form a large part of the internet’s infrastructure, told through the lens of a repair ship crew’s activities before and after the 9.1-scale earthquake that devastated Japan in 2011. Like they say in the rewilding article, redundancy !== diversity. Off the back of this article, I need to read “Rethinking Repair” by professor Steven Jackson.

***

Mandatory interoperability, federated “social” accounts for infrastructure and public services, levying major search engines to publicly finance key internet infrastructure, user-enabled global privacy control for all… a girl can dream.

Published

Inexactly benchmarking Eleventy vs Astro build times

The Eames Institute team is checking out some frameworks and static site generators for a project, and I wanted to see how Eleventy and Astro compare in terms of build time.

Zach Leatherman’s 2022 article “Which generator builds Markdown the fastest?” is probably the most thorough resource I’ve come across along these lines, and I’d recommend checking that out if you want to do some serious comparisons.

But I was curious about a “real world” test in 2024, so I decided to do some inexact benchmarking using a Markdown export of this blog. A caveat up front: I’m much more familiar with Eleventy than I am with Astro, which will likely be apparent when I get to the incremental build tests later in this post.

For Eleventy I used eleventy-netlify-boilerplate with zero modifications, and for Astro I used the blog template as described in their docs with some small modifications along the lines of this wordpress-to-astro repo to get categories and tags working. I didn’t want to use wordpress-to-astro directly since it was last updated two years ago, but it is a good reference point.

My blog has 770 posts which were exported to 770 Markdown files. With a paginated feed, categories, and tags, the total number of built pages is around 2550.*

Based on an average taken from 10 builds, Astro took 10.07 seconds and Eleventy took 4.29 seconds to build.

Incremental builds can speed things up significantly since the only built content is that which is relevant to the modified files.

Eleventy has supported incremental builds since December 2022 (I believe!), but it doesn’t yet support it on a CI server. There is an open issue for it which looks like it has traction.

To test incremental builds, I added and removed the same single tag on the same post 10 times.** Based on an average taken from 10 incremental builds, Eleventy took 2.17 seconds skipping 777 files. I would have expected it to skip more, but this might have to do with not being able to incrementally build paginated data.

I wanted to test the same content change in Astro… but it isn’t clear to me that there is an apples-to-apples comparison. Astro introduced an experimental Incremental Content Caching feature in v4.0 (not sure if this is supported on CI servers). When I added experimental.contentCollectionCache to the config, there was no difference between basic build times when I made a content change. I’m not sure if this is because having all of my content in Markdown makes the caching a mute point, or if it’s something else. If anyone has further context on how best to test Incremental Content Caching in Astro, would love to know.

For what it’s worth, running astro dev is extremely quick, just 125ms before it’s ready.

I’d be curious to do a similar benchmark using WordPress’s REST API but am not sure I’ll have the time… Will update here if I do.


* I give a rough number because the Eleventy boilerplate and Astro template generate a few additional pages, but the page total difference is in the single digits so I didn’t waste time evening them up perfectly.

** For my own future reference in case I do further tests: Add and remove the tag hello from this post.

Published

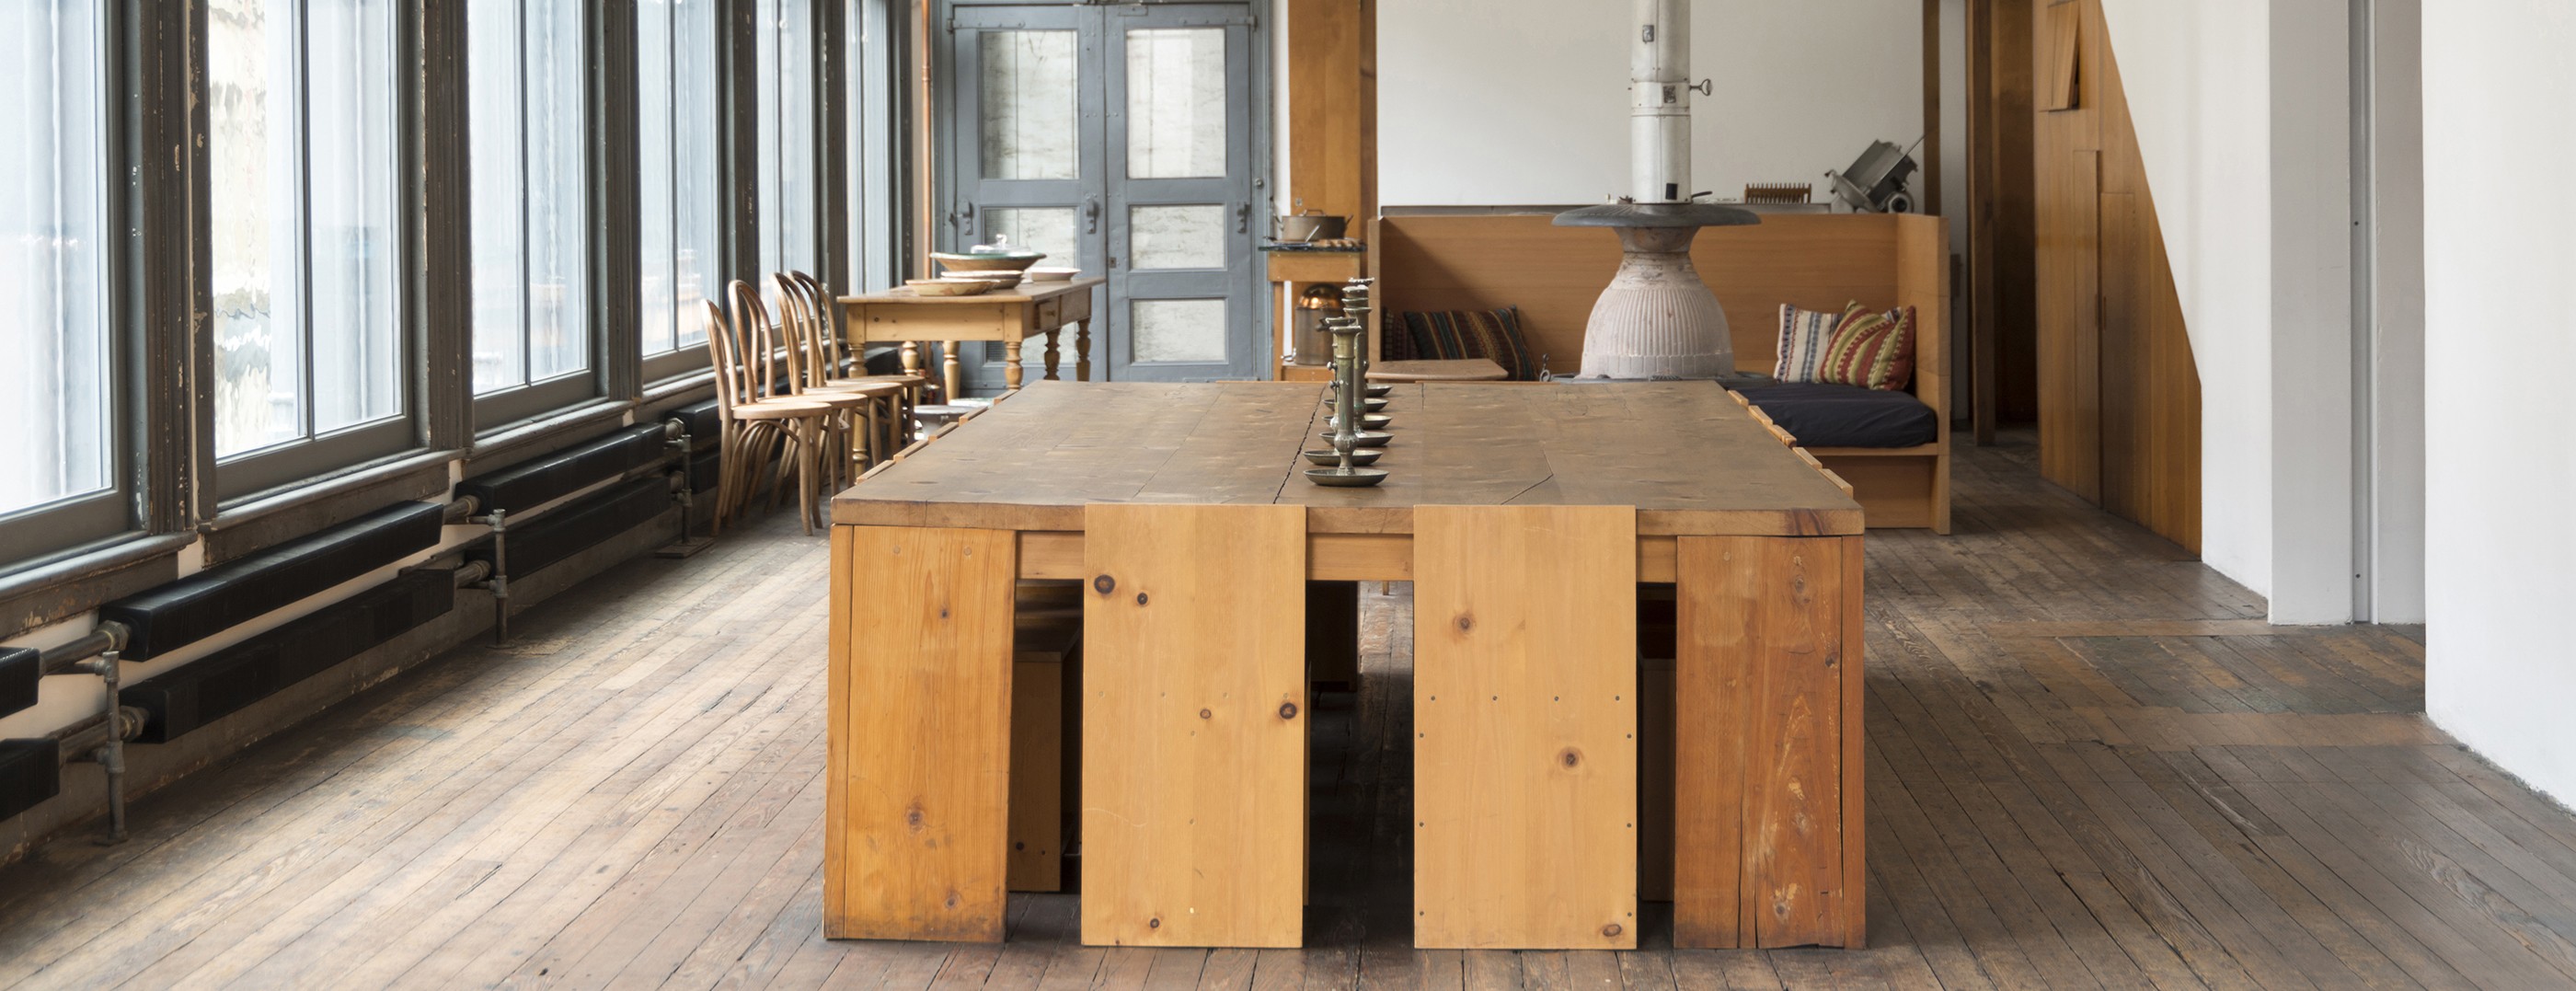
Some thoughts about making a Donald Judd-esque table

Most of the NYC crew from the Eames Institute took a little field trip to 101 Spring Street yesterday. There was a lot I found beautiful, and a few things that gave me pause.

But one of the things I most enjoyed inspecting was Donald Judd’s big 14-seater whitewood table in the kitchen / dining space on the second floor. Clearly well-loved, and slightly more rough-and-ready than some of his other furniture. It was good fun to have a close look at the dining chairs too, though I’m more interested in the form there. Don’t look too comfortable.

This is a very broad overview of some points to consider if I ever want to make a Judd-esque table.

Read more

Published

Color contrast tools to check against APCA

EL introduced me to contrast.tools recently, it uses the Advanced Perception of Color Algorithm (APCA) to check the accessibility of your text based on the desired colors and the font weight + size. But importantly, it also provides a lookup table to verify how you should (possibly, probably) interpret things.

I think that APCA is being floated as the new contrast algorithm for WCAG 3.0? But I’d need to look in to it more to be sure. Apparently APCA Readability Criterion (ARC) might be a new standard for visual contrast.

Side note: I kind of wish we could get away from acronyms-within-acronyms-within-acronyms in the accessibility standards world…

Published

SUCCESSFUL Adventures in setting up ActivityPub + Webfinger on a Flywheel-hosted WordPress site

Updated 31 October 2023 at 2:45pm to edit the NGINX config and give a further explanation.

I gave up too soon!

Emerson from Flywheel did more digging in the Fastly cache documentation and realized that we could tweak the NGINX config to fully support content negotiation. He added a Vary header to the necessary URLs et voilà, everything started working properly. Now, courtesy of Matthias Pfefferle’s great WordPress plugins and Flywheel’s dogged help, you can follow this blog on Mastodon if you search for @blog@piperhaywood.com or https://piperhaywood.com/@blog.

For future reference, this is the NGINX config tweak that got ActivityPub and Webfinger working on Flywheel with their Fastly caching setup:

location ~* /.well-known/webfinger {
    default_type application/activity+json;
    add_header Vary Accept;
    include internal-proxy.conf;
}

location ~* / {
    add_header Vary Accept;
    include internal-proxy.conf;
}

It’s fairly self-explanatory, but essentially the first location block ensures that all Webfinger endpoints have a default content type of application/activity+json, adds a Vary HTTP header so that Flywheel’s caching via Fastly will cache different versions of the page depending upon the content type, and includes further configuration via an internal-proxy.conf file. The second location block ensures that all URLs across the site basically do all of the above, but no default content type is set. (TBH I feel like I might only need the second block… but at this point everything is working nicely so I’m not going to ask the kind souls at Flywheel to change the config yet again!)

Colin from Flywheel explained the internal-proxy.conf file to me in my far-too-long support ticket:

The internal-proxy.conf is indeed an internal file that has platform-specific rules. Some of this config file is just simple cache rules, excluding common paths, whereas other parts are potentially sensitive as they pertain to our load balancing and proxy configs.

So that’s it! You can follow this blog now on Mastodon, and all blog posts published after October 30th should show up.

Published

Adventures in setting up ActivityPub + Webfinger on a Flywheel-hosted WordPress site

Update: We got it working! Take a look at this post for more.


I recently moved my hosting from NFSN to Flywheel. NFSN had served me beautifully for years, very economically, but I just don’t have as much time for admin anymore and Flywheel’s managed WordPress hosting was a useful move to cut down on that stress.

Alongside the hosting move, I’ve been trying to set up the very talented Matthias Pfefferle’s ActivityPub and Webfinger WordPress plugins to get this site on Mastodon.

Unfortunately, Flywheel doesn’t seem to play super nicely with the plugins. Part of this is Flywheel’s NGINX configuration which they lock down tight with good reason. But the bigger sticking point is Flywheel’s full-page caching mechanism. Though their caching provider supports content negotiation, Flywheel itself does not. This causes issues where JSON can end up being cached instead of HTML on various pages, most notably the homepage. (Apologies if you saw a JSON blob when visiting this site recently!) We tried to get around this by forcing the content type on the homepage and Webfinger endpoints, but JSON was still served up on the homepage whenever a client sent through a header with Accept: application/activity+json.

For now, I’ve deactivated the plugins. I’m hoping that Flywheel might look in to supporting them more broadly, but that realistically depends on demand from their customers. For posterity since I hope to revisit this in the future 🤞, here is the discussion about all of the above within the Webfinger repo, including some tips from Matthias.

Flywheel’s support staff have been pretty fantastic through all of this and I’ve been really happy with the hosting thus far so I’m not tempted to move hosts (again) for this. Not yet at least!

Published

Thoughts on search, AI as a rubber duck, and this blog

I’ve been working on a little side project recently that has been in the backlog for ages. I finally have a moment to pull it together, and it’s helping me brush up on a few Next.js 13 features I haven’t had the chance to play with yet.

As part of that, I’m doing a lot of searching around best practices on this that and the other, particularly server side rendering. It’s the first time in a while that I’ve been pointedly trying to use the internet to teach myself something in-depth related to coding, as opposed to finding quick sporadic answers.

Read some rambling thoughts on search 🔍, AI as a rubber duck 🦆, digital gardens 🪴, and the future of this blog 🧠

Published

Dave Rupert’s animation-timeline example

See Dave Rupert’s post on scroll shadows with animation-timeline. Browser support isn’t quite there yet so it’s more of a progressive enhancement, but this is a great use case example.

He wrote that off the back of Bramus’s scroll-driven animation exploration, and wow. So many of those behaviors would have been useful on past projects…